Blog
Cloud-Native Insights & Expertise

Discover our latest articles about cloud-native technologies, Kubernetes, DevOps, and modern software development. From practical tutorials to in-depth analyses.

Latest Blog Posts

Stay up to date with our latest articles about cloud-native technologies, Kubernetes, and DevOps.

1219 posts

Old Iron, New Shell: How to Modernize Legacy Monoliths with Kubernetes Sidecars

Old Iron, New Shell: How to Modernize Legacy Monoliths with Kubernetes Sidecars

"We can't move that to the cloud, it's a monolith." We hear this sentence often. However, modernization in 2026 doesn't necessarily mean breaking down a mature Java or .NET application into tiny microservices (refactoring). Often, the faster and more economical route is **re-platforming** using the **sidecar pattern**.

K8s at the Point of Sale: Why Manufacturing and Retail are Turning to Edge Clusters

K8s at the Point of Sale: Why Manufacturing and Retail are Turning to Edge Clusters

For a long time, Kubernetes was considered the operating system for the "big" data center. But in 2026, the most exciting developments are happening at the network's edge. Whether it's image processing in a factory's quality control or inventory management in hundreds of retail stores, centralized cloud solutions are reaching their limits.

Supply Chain Security with SBOM and Sigstore

Supply Chain Security with SBOM and Sigstore

Imagine buying a ready-made meal at the supermarket without an ingredient list. For years, this was the standard in software development: we download container images from the internet and trust that what's inside matches the label. However, incidents like *Log4j* have shown that a single compromised library in the supply chain can cripple global infrastructures.

Serving at the Limit: LLM Inference with vLLM and Triton on Kubernetes

Serving at the Limit: LLM Inference with vLLM and Triton on Kubernetes

When an AI model leaves the training phase, the real challenge begins: productive inference operation. Serving a Large Language Model (LLM) in a standard container is inefficient. Latencies are too high, and GPU utilization is often poor because traditional web servers are not built for the sequential nature of token generation.

Vector Databases on K8s: Performance Tuning for RAG Applications

Vector Databases on K8s: Performance Tuning for RAG Applications

In a Retrieval Augmented Generation (RAG) architecture, the vector database (Vector DB) is the core component. It provides the Large Language Model (LLM) with context from your enterprise data. However, while traditional databases are primarily optimized for disk I/O, vector databases like **Qdrant, Weaviate, or Milvus** impose entirely new demands on your Kubernetes infrastructure.

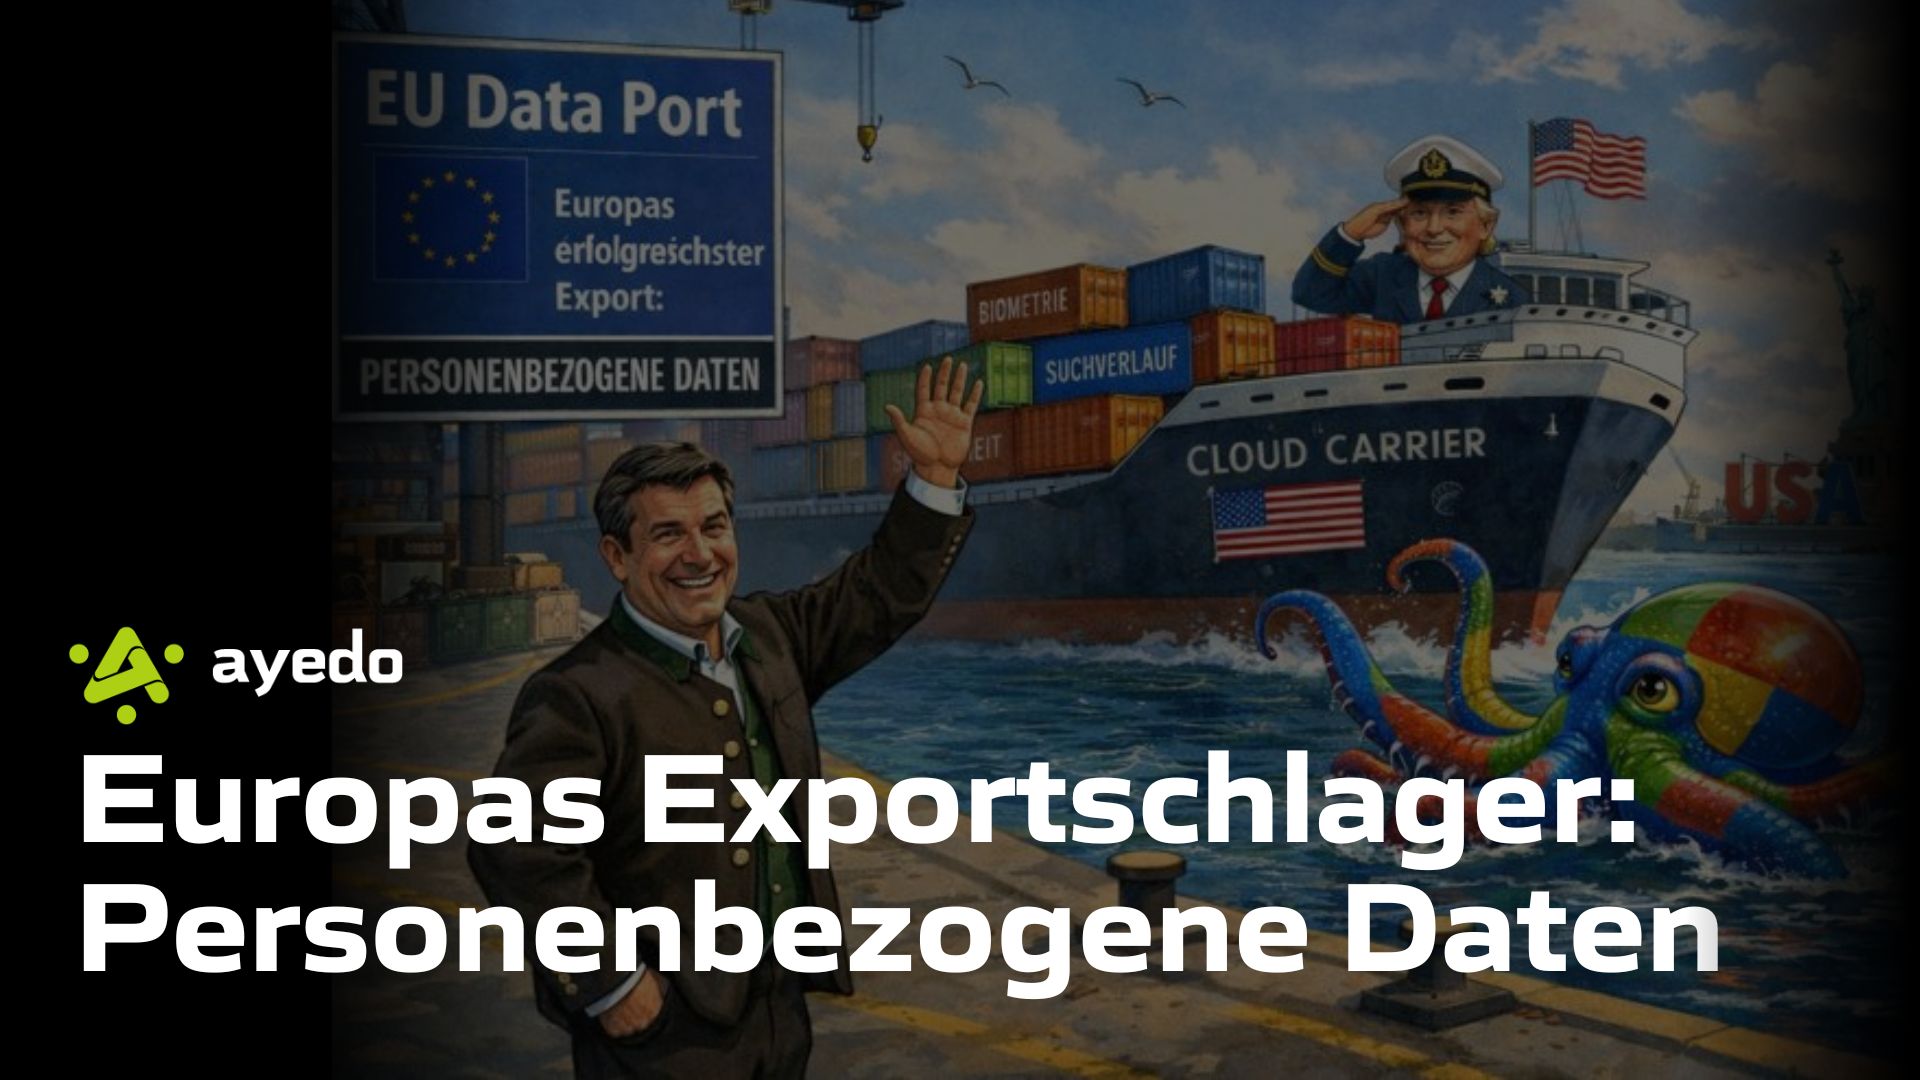
Europe's Export Hit: Personal Data

Europe's Export Hit: Personal Data

Europe likes to see itself as a global guardian of data protection and fundamental rights. GDPR, NIS2, AI Act – the regulatory claim is high, the rhetoric confident. In operational reality, however, a different picture emerges: personal data of European citizens and companies is systematically outsourced to infrastructures lying outside European legal and control spheres. Not illegal, but politically shortsighted. Not out of necessity, but out of convenience.

Advanced GPU Strategies for Efficient AI Clusters

Advanced GPU Strategies for Efficient AI Clusters

Integrating an NVIDIA H100 or A100 into your cluster today quickly reveals that the classic 1-to-1 allocation (one pod reserves an entire GPU) often results in massive capital waste in a production environment. While training LLMs fully utilizes the hardware, GPUs often idle at 10% utilization during inference operations or in development environments.